3:37
MoE on CPU: 13B-Class Answers at 3B Speed
Inventive HQ
3:10
Bigger Draft Model = Faster? A Speculative Decoding Sweep
More CPU Threads Made My LLM Slower: A Thread-Scaling Test
3:19
I Capped My GPU to 150W and Barely Lost Any Speed
Flash Attention in llama.cpp: -fa Is Free Because It's Already On
3:35
The Context-Length Tax: What Going 2K to 32K Actually Costs
3:21
The VRAM Cliff: 15× Slower the Moment Layers Spill to CPU
3:38
KV-Cache Quantization: The q4_0 Cliff Your Logs Won't Warn You About
3:59
How Low Can You Quantize a GGUF Model Before Quality Breaks?
3:46
Ollama vs llama.cpp vs LM Studio: The Speed Tax, Measured
3:54
llama.cpp Speculative Decoding: Does It Work on Cheap GPUs?
6:53
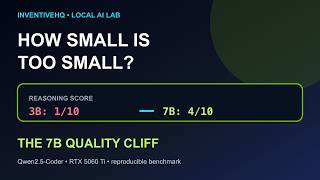
How Small Can a Local LLM Get Before It Stops Reasoning?